Your design system lives in two places. One is the file: Figma variables, a token JSON, a page of swatches somebody signed off. The other is the code that actually ships, and that's the one your readers see. Teams review the first one constantly. Almost nobody audits the second.
That gap is what the aosf-design plugin for Claude Code is built to close. Its skill, ui-audit-consistency, reads your tokens, reads the HTML and CSS built against them, and tells you where the two disagree. It also checks the built page against WCAG 2.2 AA, which no design contract gets to waive.
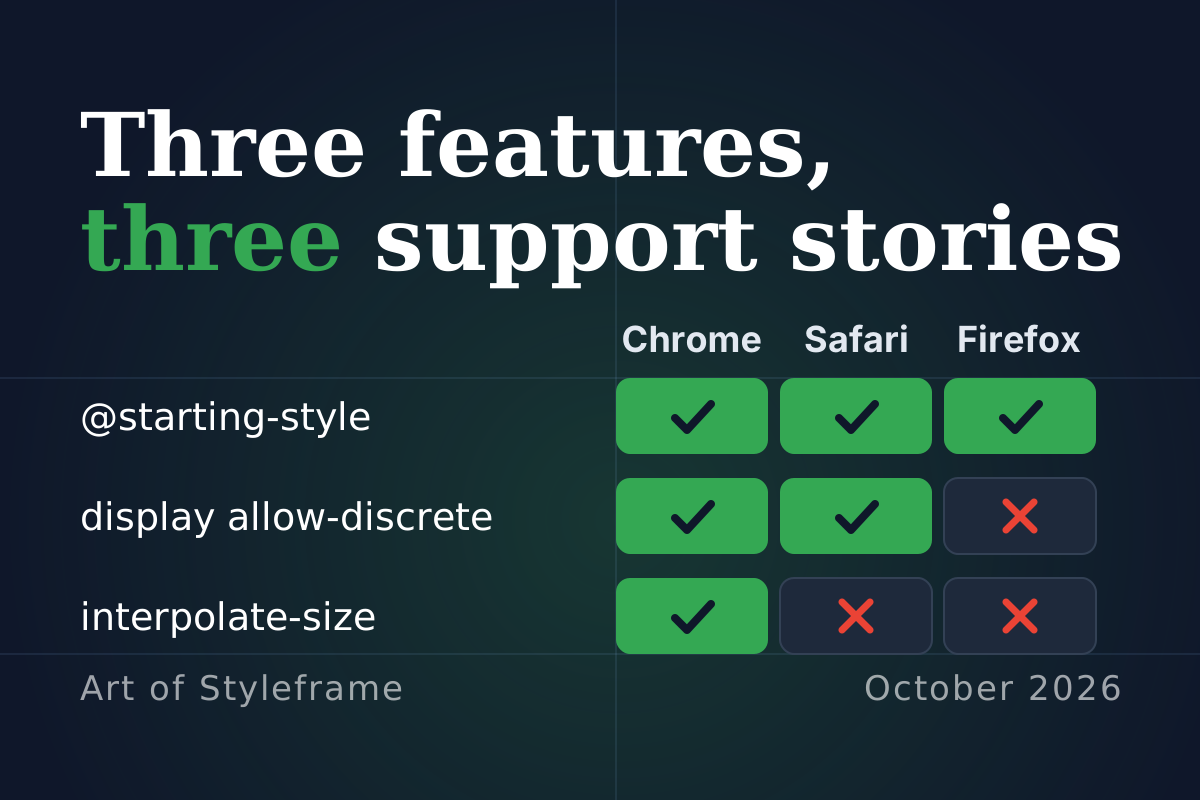
TL;DR: Install the plugin with two commands inside Claude Code, point it at your source folder or a live URL, and it reports token drift and accessibility failures as separate scores with a rule ID on every finding. We ran it on artofstyleframe.com on 2026-10-16. The interesting part wasn't only what it found on the site. It was what the tool itself got wrong, how we checked, and what it took to move token compliance from 35.4% to 97.8%.
Why Does Nobody Check the Code Half of a Design System?
Because the code half doesn't look like a design artifact. A token file is reviewed in a pull request by an engineer who checks that it compiles. A component stylesheet is reviewed by whoever touched it last. Nobody opens the built site with the token list in one hand and asks, line by line, whether 0.85rem was ever a size the system agreed to.
So drift accumulates quietly. A hard-coded hex here, a fallback that made sense two redesigns ago there. Each one is small. Together they decide whether your design system is a system or a suggestion.
We've written before about getting tokens from Figma into CSS and Tailwind and about where Figma variables end and tokens begin. Both pieces are about the handoff. This one is about the morning after: once the tokens are in the code, does the code still use them?
What Does the Plugin Actually Check?
Two different things, and it keeps them apart on purpose.
The first class is called contract. That's your own tokens and design notes. A violation is drift: the build left what was approved. If your contract says a 4px spacing base, then 4px is correct and 6px is drift, even though nobody outside your team would call 6px wrong.
The second class is called floor. That's WCAG 2.2 AA plus a short list of universal anti-patterns, and no contract can waive it. A palette can be perfectly on-brand and still put 2.9:1 text in front of a reader. The contract decided the palette; it didn't get to decide that the text is legible.
Every finding cites a rule. Version 0.1.0 shipped with 78 of them, each with a stable ID carrying the DSG- prefix and a named source, and our audit added a 79th (more on that below). The rule that impressed me most is the one about what happens when there's no rule: a defect that matches nothing goes under Observations and scores nothing. The skill's own phrasing is "never invent a rule." That single constraint is what stops an automated design review from drifting into taste.
Scoring follows the same discipline:
- Three separate scores: Design, Accessibility and Consistency. They're never averaged into one number, because a beautiful page that fails contrast isn't a B-minus.
- Four severity tiers, deducted from 100: Blocker -12, Critical -8, Warning -4, Tip -1.
- "No clause, no blocker." A Blocker has to cite a WCAG success criterion or a legal clause. Strong opinions top out at Critical.
- One root cause counts once, however many nodes it touches. Forty buttons sharing one bad color is one finding, not forty.
Contrast is where the two classes meet most often, so it's worth seeing the numbers before going further.
How Do You Install and Run It?
Inside a Claude Code session, add the marketplace and install the plugin. The repository is public, MIT-licensed, and is a marketplace with exactly one plugin in it:
/plugin marketplace add artofstyleframe/aosf-design
/plugin install aosf-design@aosf-design
Then run it on a folder, a glob, or a URL:
/aosf-design:ui-audit-consistency src/We checked that the install works from a clean Claude Code config on 2026-10-16. Asking in plain words also triggers the skill ("audit this page against our design tokens" does it), but the explicit command is easier to repeat and easier to put in a team's runbook.
Static, Live or Screenshot?
The skill has three modes, and picking the wrong one is the most common way to get a misleading report.
| Mode | What it reads | What it needs | What it can't see |
|---|---|---|---|
| Static (default) | Source files: HTML, CSS, Astro, JSX, TSX | Nothing extra | Computed contrast after the cascade, real focus order, anything rendered at runtime |
| Live | A rendered URL, via Playwright and axe | playwright and @axe-core/playwright | Hover, focus and dark mode; it measures the default state only |
| Screenshot | An image of the page | Nothing extra | Everything below the pixels; it judges hierarchy only, with no file:line findings |
Under the hood the numbers come from scripts, not from the model's estimate. They're plain Node scripts with nothing to install: contrast_checker.mjs for token pairs, token_extractor.mjs to pull tokens out of CSS, Tailwind or JSON, token_validator.mjs to measure how much of the code actually uses them, and rules_lint.mjs to check that the rule registry doesn't contradict itself. Live mode adds live_audit.mjs, the only one that needs Playwright. The scripts exit 1 on a blocker, so you can wire them into CI without the model in the loop at all.
My honest recommendation: run static first, then live. Static is fast and shows you drift. Live is the only one that can tell you what the reader's browser actually painted.
What Did the Audit of Our Own Site Find?
We pointed it at artofstyleframe.com on 2026-10-16. The contract was .design-sync/tokens.css, a mirror of the skin defined in our blog config. There was no tokens.json and no DESIGN.md, which is probably typical for a site that grew rather than being specified.
The accessibility floor came back clean, and I'll admit that was a relief. Live mode loaded seven pages (home, the blog index, our top article, a designer page, a styleframe page, the tools index and the 404 page) at three viewports, 1440, 768 and 375 pixels wide. Twenty-one runs, zero axe violations.
One item was flagged and correctly not scored: the footer wordmark, four spans, only on mobile, was reported as a logotype candidate. WCAG 1.4.3 exempts text that is part of a logo or brand name, so the tool reported it and moved on. That's the right behavior. A tool that silently skipped it would be hiding something; one that scored it would be wrong.
The token contrast check covered 34 color pairs with zero AA failures. Seven more were marked "candidate": pairs the script inferred from token names rather than found in use. Those are advisory, and treating them as failures would be a mistake.
Then came the number that looked bad. How bad? Token compliance started at 35.4%: 1,199 values went through a token and 2,190 were literals. What sat behind it, in the order we found it:
The Contract Lagged the Skin
--radius-pill and the other radius tokens existed in the skin, and the site used them. They just weren't in the contract file. So 39 perfectly correct uses read as "undefined token." Thirty-nine findings, one stale file. Whose fault was that? Ours, not the tool's. Before you trust any drift number, check that the contract is current.
Twelve Tokens That Were Never Defined
This one was real. Twelve tokens, among them --c-muted, --c-surface-2, --c-bg-muted and --c-hairline, were referenced with a hard-coded fallback and defined nowhere. Every one of those fallbacks rendered every time. The code looked tokenised and wasn't.
We defined them in the skin with values equal to the old fallbacks, so nothing on screen changed. Where a new name duplicated an existing token holding the identical value, we pointed it at that token instead of minting a twin.
Fallbacks That Disagreed With Their Own Tokens
This finding didn't exist as a rule when we started, and it's now DSG-TOK-11. We found 71 var(--token, fallback) expressions where the fallback disagreed with the token it falls back from. The clearest example:
/* The pattern as we found it, selector simplified.
   The token holds #64748b; the fallback is a lighter grey. */
.muted-text {
  color: var(--c-text-muted, #94a3b8);
}
On white, #94a3b8 measures 2.56:1. The token's own value, #64748b, measures 4.76:1. Where the token is defined, the token wins and the text passes. But our tool embeds can render outside the main stylesheet, and there the fallback was painting a grey that fails AA. Nobody chose that grey for that context. It was simply left over.
We aligned all 71 fallbacks with their tokens. The site itself didn't change, because on the site the token always wins. That's exactly why the bug survived: the place where everyone looks was fine.
What Did the Tool Get Wrong?
Quite a lot, and this is the part I'd ask you to take seriously. An audit tool produces false positives. The useful habit is to check each finding against the code before fixing anything.
A hex-shorthand bug. The validator didn't expand #fff to #ffffff, so a white that matched a token exactly was reported as an off-token literal. One component produced 183 false findings from that alone. Had we "fixed" them in the CSS, we'd have touched 183 lines to change nothing.
Shorthands judged as one literal. A declaration like margin: 0 0 1rem was treated as a single untokenised value, even when 1rem is a scale step. Worse, 24px and 1.5rem were treated as different lengths. They're the same length at the default root size. We fixed both in the validator, and compliance went from 43.9% to 55.7% without touching the site again. Twelve points of "progress" that were really twelve points of measurement error, corrected. Would a dashboard have told us the difference? No.
One false positive and two deliberate exceptions. A token defined locally on a component was flagged as undefined. Two animation variables are set at runtime by script, so no static file can define them. All three now sit in a documented exceptions list rather than being forced into a shape they don't fit.
Two claims we retracted. The first live run reported 183 console errors on one article. We couldn't reproduce them on a plain page load, so the claim went. It also reported a page that never reached network idle. That turned out to be a Cloudflare challenge served to the automated browser, which is the CDN doing its job and not a defect on the page.
Does this make the tool untrustworthy? I don't think so. It makes it a tool. Every one of those mistakes was visible because each finding cites a rule and a file:line, which means each one can be checked in under a minute. A design review that says "the spacing feels inconsistent" can't be checked at all.
The Last 42 Points Were a Decision, Not a Cleanup
After the contract, the undefined tokens and the validator fixes, compliance sat at 55.7%, and I wanted to know why it stopped there.
About 82% of what remained was spacing and font sizes that sit between scale steps. There were roughly a dozen near-duplicate font sizes between 0.66rem and 1.05rem: 0.7, 0.72, 0.78, 0.82, 0.85, 0.9 and 0.95rem among them. None of them was a token. Each had been chosen by someone looking at a specific component, and swapping any of them for the nearest token would visibly change how that component looks.
So this wasn't a find-and-replace job. It was a decision about the scale, and a decision needs someone allowed to change the pixels. We got that permission on 2026-10-16, and made it.
- Type: eleven steps, 12, 14, 16, 18, 20, 24, 28, 32, 40, 48 and 64 px, each a token.
- Spacing: a 4 px base with fourteen steps from 4 to 128 px.
- Radius, shadow and layering: four radius steps plus a pill, three elevations with a hairline ring, and named z-index layers.
- Status colors: warning, success, error and info became tokens, because several tools used them for the same meaning.
Every old value snapped to the nearest step, ties rounding up, and was written as var(--fs-14, 14px), so an embed that renders without the skin still paints what it always did. Translucent colors became color-mix() of a token instead of an rgba() literal. The cost is real: things moved by one or two pixels, so the visual regression baselines had to be regenerated before the next deploy.
Where did the figure land? With the same validator measuring both, the site before the scale work scored 55.4% (55.7% under the earlier build of the validator) and the site after scored 97.8%. Declaring 19 exceptions in the contract (the Pinterest, LinkedIn, Bluesky and Facebook brand colors, the sample palettes a color tool displays, and hue-driven avatar gradients that are data, not styling) covers the last 76 uses and gets the report to 100%. Roughly twenty points came from fixing the validator and forty-two from changing the site. That split is the number I'd want to see on any audit report, and the one most of them leave out.
Here's the opinion, and plenty of design system teams will disagree with it: a percentage reached by exceptions is only worth something when every exception carries a written reason. Without that, 100% is a sum of nothing. The figure measures how much of the code goes through tokens. It doesn't measure whether the design is any good, and a codebase can reach 100% by inventing a token for every stray value, which produces a system nobody can hold in their head.
Token compliance measures how much of your code goes through tokens, not whether your design is any good. A well-chosen scale with documented exceptions beats any percentage.
If you're facing the same decision, our type scale calculator shows quickly whether a ratio lands near the sizes you already use, and our piece on an 8pt spacing scale for long-form layouts covers the spacing half.
What It Won't Tell You
Every limit here is one the plugin states about itself, which I count in its favor.
Static mode can't see computed contrast after the cascade, real focus order, or anything that only exists at runtime. Live mode measures the default state only. Hover, focus and dark mode are unmeasured, which isn't the same as passing. If your dark theme was never loaded, the report has nothing to say about it, and it shouldn't be read as saying "fine."
None of this replaces watching a real person use the page. Every rule is a proxy for a human outcome, so a pass is a floor, not a verdict. For the parts no script catches, our UX audit checklist is still the better instrument. And if contrast is where your system keeps failing, baking WCAG into the tokens themselves prevents the problem upstream, which beats detecting it afterwards.
If you'd rather start with a cheaper, repo-level check, our design system health scorecard runs in a third of a second with no plugin.
A Workflow That Holds Up
What we'd repeat, in order:
- Check the contract first. Make sure the token file the audit reads matches what the site actually defines. A stale contract inflates every drift count.
- Run static, then live. Static for drift across the codebase, live for what the browser painted at each viewport.
- Read Observations separately. They're defects with no rule behind them. Some matter; none are scored. Treat them as a reading list, not a backlog.
- Verify every finding against the code. Open the
file:line, look at the value, and decide whether it's a real problem, a tool bug or a documented exception. - Write exceptions down. Brand colors and sample data are legitimate, but only with a reason in the contract file, so the report counts them instead of ignoring them.
- Fix in waves. The skill's fix mode goes blockers, then criticals, then warnings, never everything in one pass. One root cause often hides behind dozens of findings, and fixing it first makes the rest vanish.
Is it worth an afternoon? For us the clean accessibility floor was reassuring, but the undefined tokens and the 71 disagreeing fallbacks were the kind of drift no human review would have caught, because the screen looked right. If you're already using Claude in your design work (our notes on where Claude actually helps designers cover the broader picture), this is one of the few places where it checks your work rather than producing more of it. And if your system is generated from a Storybook, as in our guide to making the repo the source for Claude Design from Storybook, this audit is the other half of that loop: the part that asks whether the code still agrees with itself.
Check a pair before you argue about it
This opens on #64748b on white, the value the token actually holds, and it passes AA for body text at 4.76:1. Now type #94a3b8 into the text field, the grey a component paints when its token is missing, the pair our audit caught hiding in a CSS fallback. Same role, same intent, and one of them fails AA for body text while the other passes.